Problem
Agent skills can sound persuasive while leaving behavior unchanged. The problem is to separate an apparent improvement from a reproducible, inspectable change under controlled conditions.
What I built
A persistent lab connecting canonical artifacts, controlled experiments, preserved run evidence, histories, reports, and verification tooling. The record keeps the materials behind a conclusion available for review.
Architecture / decisions
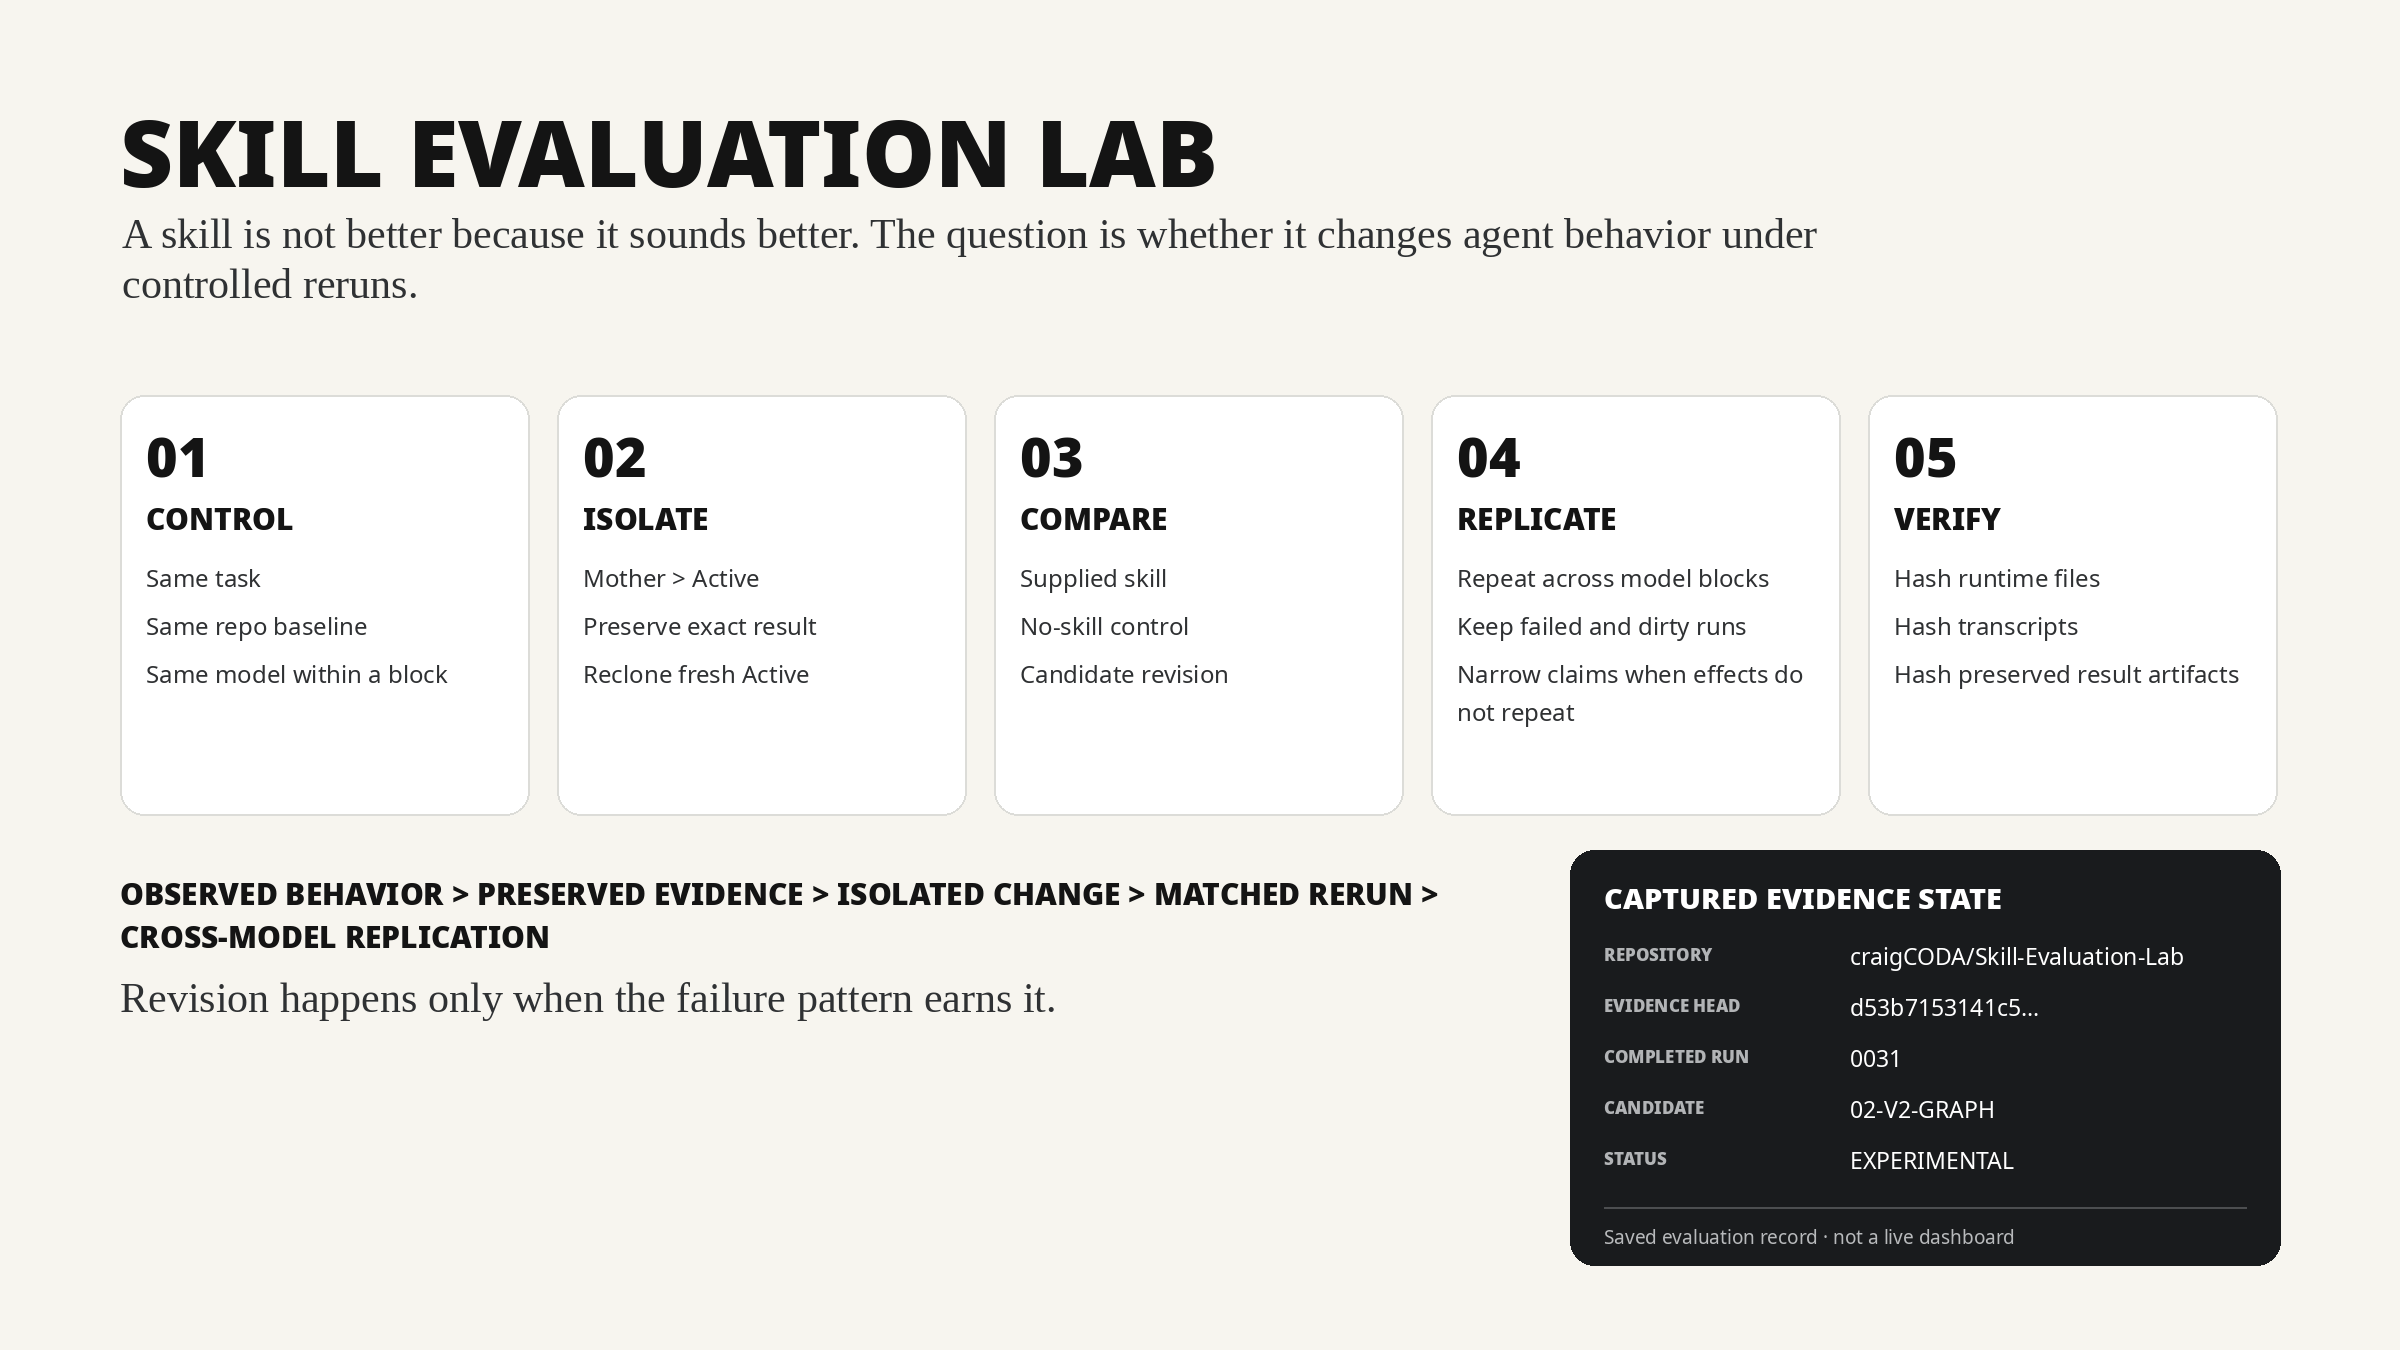
The sequence is deliberately linear: control the inputs before interpreting the result.
- ControlHold prompt, baseline, model, and harness conditions constant.
- IsolateKeep immutable Mother artifacts separate from disposable Active run state.
- CompareRun original, no-skill, and candidate conditions with one global run identity.
- ReplicateRepeat across models instead of treating one favorable run as a broad effect.
- VerifyHash result state and transcripts, then retain command output for verification claims.
Evidence
Preserved failures remain in the record before cleanup. Exact result state supports outcome claims; transcripts support process claims; command output supports verification claims. SHA-256 manifests make the saved materials checkable.
A failed condition has the same evidentiary weight as a favorable one: it can narrow or reject a claim.
Result
Evidence can support, narrow, or reject a behavioral claim. Effects that do not reproduce do not become general claims.
Technologies
- Repository workflows
- Python verification tooling
- SHA-256 manifests
- Structured experiment records
- Agent harnesses
Current boundary / unfinished work
Experimental candidates are not promoted as general improvements. The image’s 0031 block is a captured saved record, not live or current repository status for the public repository. Its confirmed public evidence release records runs 0001–0015.